Networking Internals: Why CDNs Fail in Ways You Don't Expect
“A CDN is not a silver bullet. It’s a distributed system — and distributed systems fail in distributed ways.”
You put a CDN in front of your application and everything gets faster. Cache hit rates climb. TTFB drops. The infrastructure team is happy. You move on.
Then one day, users in Southeast Asia report your site is broken. Your monitoring shows green. Your origin server is healthy. But a subset of your users can’t reach you — and the failure is happening somewhere between them and you, in infrastructure you don’t own and can’t directly inspect.
Welcome to CDN failure modes.
What a CDN Actually Is
A Content Delivery Network is a globally distributed network of PoP (Points of Presence) — edge servers positioned close to end users. Requests get served from the nearest edge node rather than your origin, reducing latency and offloading traffic.
Simple in theory. Complex in practice. Because a CDN isn’t just a cache — it’s a routing layer, a TLS termination point, a DNS resolver, a WAF, and in some cases a compute platform. Each of those layers can fail independently.
The Failure Modes Nobody Tells You About
Cache poisoning. When your Cache-Control headers are misconfigured, a CDN can cache a response it shouldn’t — a 500 error, a redirect loop, or worse, a user-specific page served to everyone. Cache poisoning doesn’t announce itself. It silently serves wrong content to every user hitting that edge node until the TTL expires or you manually purge.
Stale content after deploys. You deploy a fix. The bug is still live for some users. Your CDN is serving the old version from cache. If your Cache-Control headers don’t align with your deploy strategy, you’ll spend an hour debugging a problem that was fixed twenty minutes ago. cache-busting with versioned asset filenames is the standard solution — but it requires discipline across the entire pipeline.
PoP-level outages. CDN providers have SLAs at the global level, not the PoP level. An edge node in Singapore can be degraded or down while every status page shows operational. Users in that region hit a failed node, requests time out, and your global monitoring misses it entirely because the rest of the world is fine. Geographic monitoring from multiple regions isn’t optional — it’s the only way to catch this.
SSL/TLS certificate issues at the edge. Your origin certificate is valid. But your CDN has its own certificate between the user and the edge, and a separate one between the edge and your origin. If either expires or is misconfigured, you get a broken HTTPS connection that your own SSL monitoring won’t catch — because it’s testing the edge certificate, not the origin-to-edge path.
Routing asymmetry. A CDN routes users to the nearest PoP based on DNS resolution and anycast routing. But “nearest” is network-topological, not geographic. A user in Mumbai might get routed to a PoP in London because of how their ISP peers with the CDN. The result is higher latency than if they’d hit your origin directly — and it’s invisible without end-to-end tracing.
The Observability Gap
“You can’t monitor what you don’t own.”
This is the core problem with CDN failures. The edge layer sits outside your infrastructure perimeter. Your APM tools, your logs, your traces — they start at your origin or at best at the CDN’s own analytics dashboard, which gives you aggregate data, not request-level detail.
Most CDN providers offer Real User Monitoring (RUM) or edge logs — use them. They’re the only way to see what’s actually happening between your users and your edge nodes. Without them, you’re flying blind on a significant portion of your request path.
What to Get Right
Set Cache-Control headers deliberately — every response type needs a conscious caching decision, not a default. Use versioned filenames for static assets so cache-busting is automatic on deploy. Monitor from multiple geographic regions, not just your own. Enable edge logging and ingest it into your observability stack. And test your CDN failover — what happens when an edge node is unreachable should be a known, practiced scenario, not a surprise.
Final Thought
A CDN makes your application faster and more resilient — until it doesn’t. The teams that get burned are the ones who treat it as a set-and-forget layer. The edge is part of your system. It fails like part of your system too.
 Most downloaded free PDF
50 Machine Learning Algorithms Cheatsheet
Blueprints of Intelligence — 50 ML Algorithms decoded
Enjoyed this post?
Stay in the loop
New posts + weekly digest, straight to your inbox.
Create a free account
- Save posts to your vault
- Like posts & build history
- New-post alerts
Comments
Add Your Comment
Related Posts
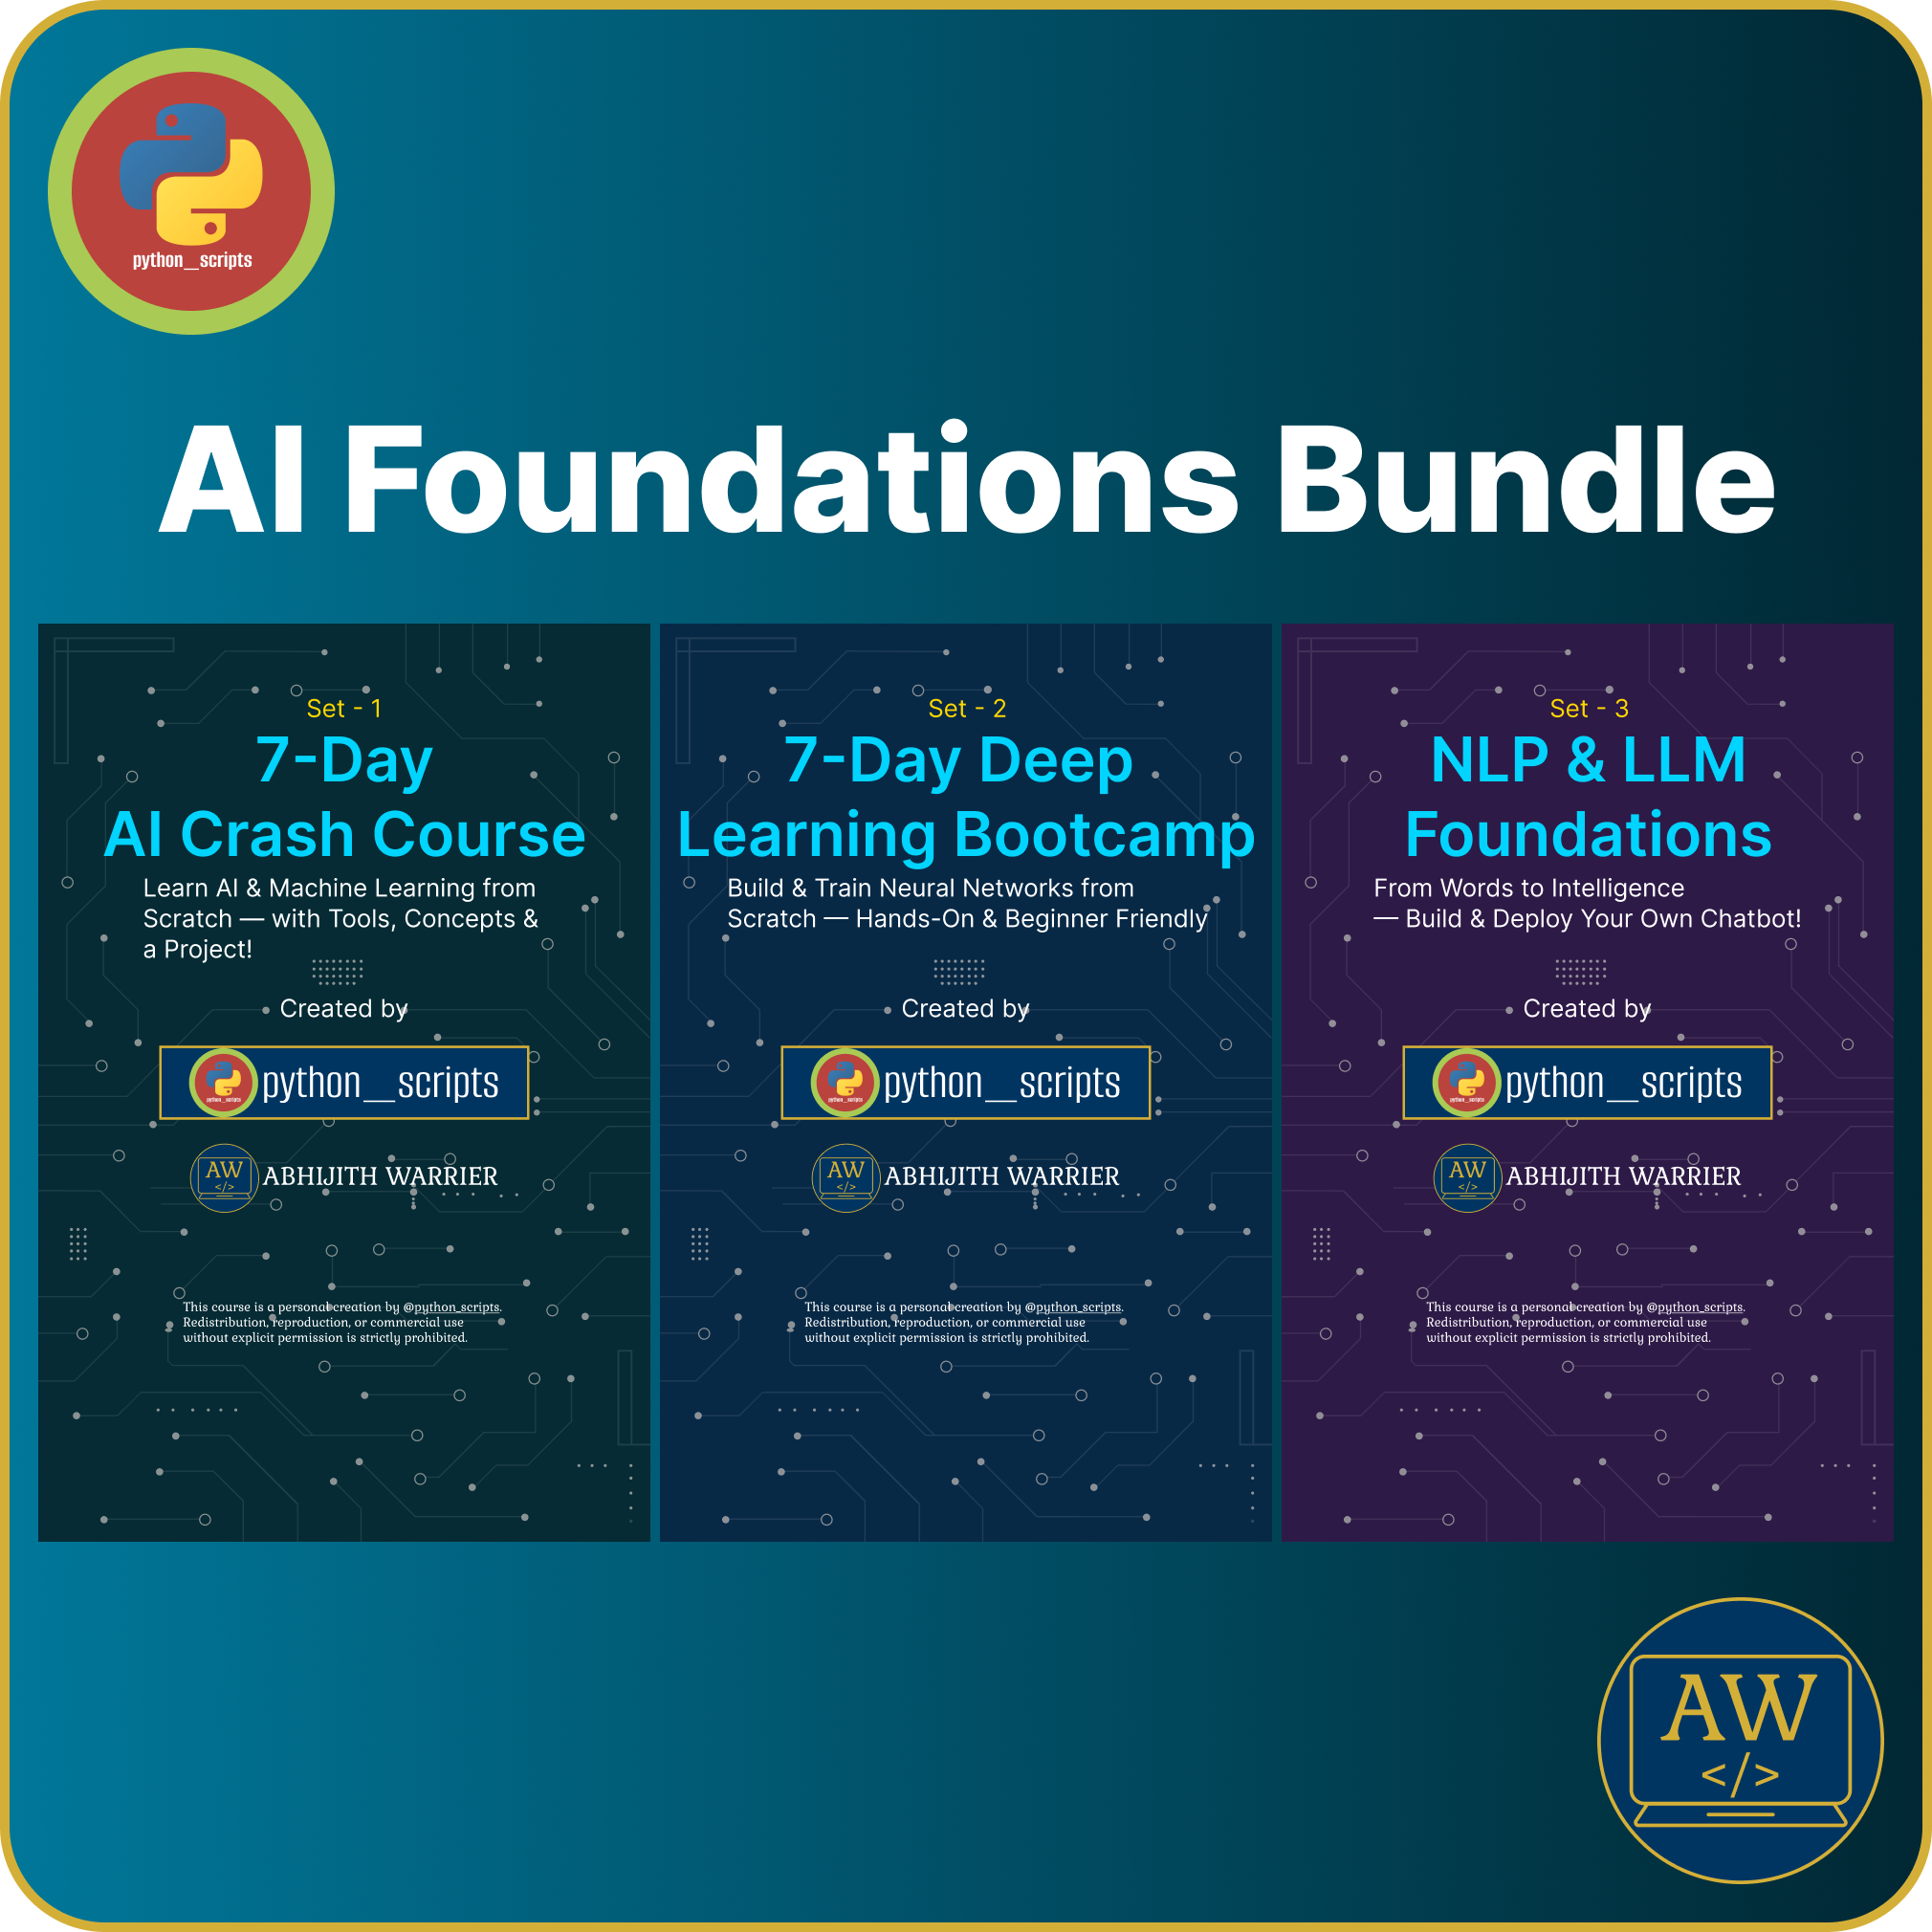
AI Foundations Bundle — From AI Basics to Deep Learning & NLP
Learn AI the right way — from core concepts to deep learning and language models, all in one structured bundle.
Ideal for beginners and developers who want a complete AI roadmap without confusion.
No comments yet. Be the first to comment!